Instrument Go Without Changing a Single Line
Talks · · 3 min

talk: Instrument Go Without Changing a Single Line

The debugging loop is slow. You cannot reproduce the bug locally, so you add a log line and redeploy. Wrong place. You do it again. An agent alone does not fix this: it still has to pick a mechanism, and it has to know what that mechanism costs. This talk is about three approaches that take the source edit out of that loop. Each acts at a different point in the software lifecycle, and each inherits the strengths and constraints of its intervention point. ...
August 13, 2026 · 3 min · 447 words · Kemal Akkoyun
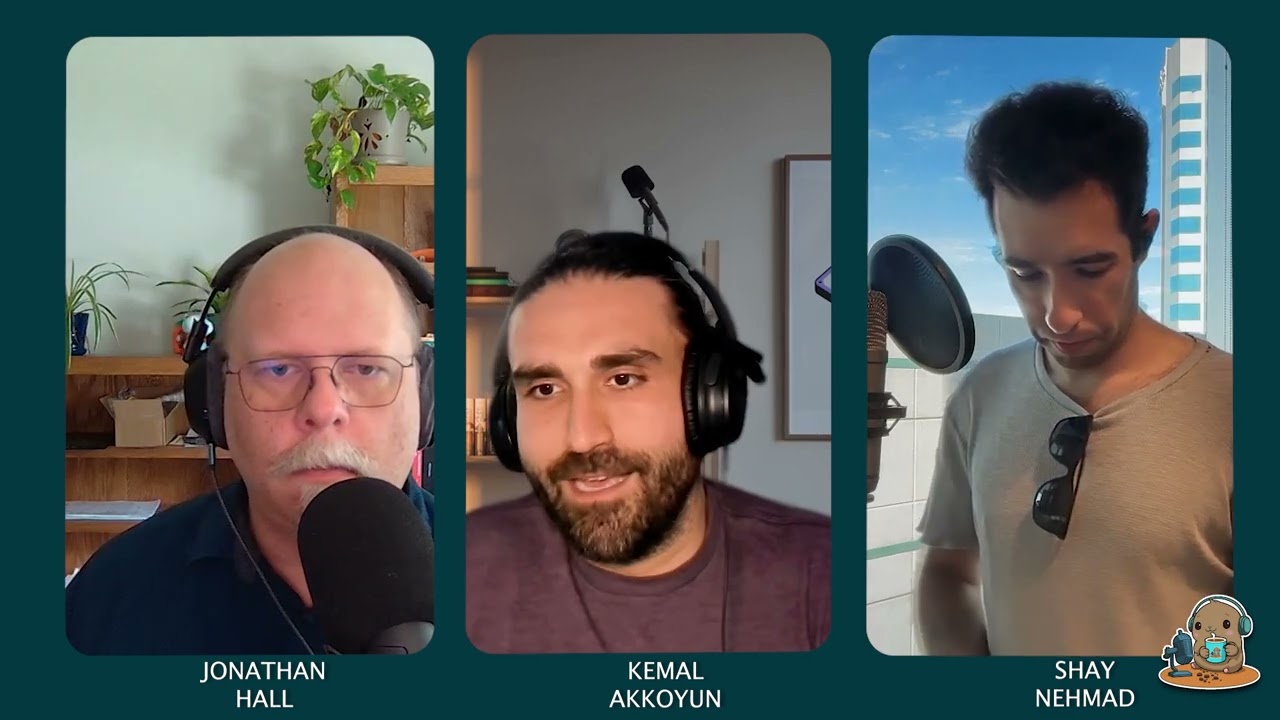
Jonathan Hall, Kemal Akkoyun and Shay Nehmad recording an episode of Cup o' Go
Talks · · 2 min

podcast: Cup o' Go — Instrumentation and Blast Radius

Jonathan Hall and Shay Nehmad had me on Cup o’ Go for episode 167, straight after their GopherCon US recap. We spent about forty minutes on instrumentation: what an APM tool is actually measuring, and the three ways you can get telemetry out of a Go program without asking every team to rewrite their handlers. The part I enjoyed arguing about most was blast radius. Manual instrumentation is precise and tedious, and it never finishes. eBPF buys you one agent covering every language on the box, at the cost of running code in the kernel, where a bad program can take the whole host down with it. Compile-time instrumentation rewrites the syntax tree behind go build through the -toolexec hook, which keeps failures scoped to one service and works anywhere Go compiles. People love this dark magic, which I find either reassuring or alarming depending on the day. ...

August 11, 2026 · 2 min · 336 words · Kemal Akkoyun
Engineering · · 9 min

Making zero-touch Go observability agent-actionable

You can’t reproduce the bug locally, so you add a log line and redeploy. Wrong place. You add another one and redeploy again. That is the debugging loop from my GopherCon UK talk, and in this last part we’re going to shorten it: a decision rule for two zero-touch tools, then a runbook an AI coding agent (not a Java-style one) can execute. The runbook starts with one boring question: is this Go service already running, or can I rebuild it? If the service has to stay untouched, OBI (OpenTelemetry eBPF Instrumentation) is the default. If I can rebuild it and need function-level spans, otelc (OpenTelemetry Go compile-time instrumentation) is the default. The rest of the decision tree is checking privileges, Go version, collector endpoint, and whether RED metrics are enough. ...

August 6, 2026 · 9 min · 1898 words · Kemal Akkoyun
Engineering · · 11 min

Three Questions Before You Trust a Benchmark

A benchmark bot once told me that one of my pull requests made a benchmark 6–9% slower. A same-machine comparison said the pull request made it faster. Both results were stable, and they disagreed. In this last part we’ll find out how that happens, and leave with three questions and three small Go tools that tell us how far to trust a number. A loose cable Physicists have been fooled the same way, at a much larger scale. In September 2011, the OPERA collaboration announced that muon neutrinos appeared to travel faster than the speed of light. Months of rechecking found nothing wrong. The root cause, eventually, was an improperly seated fibre-optic connector in the GPS timing chain, which introduced a ~73 ns bias that made neutrinos appear to arrive early (Science called it a loose cable). A second fault, an oscillator defect, pushed the other way and partly masked the first. Once both were corrected, the 2012 re-measurements showed neutrino speed consistent with the speed of light. ...

August 4, 2026 · 11 min · 2271 words · Kemal Akkoyun
Engineering · · 8 min

A/B is the wrong model for CI

We’re going to take one benchmark and stop looking at it as a pair of numbers. First we’ll see why a pair misleads, then we’ll build a small time series and read it. Start with a pair that misled me. On dd-trace-go #4891, the benchmark bot’s comment now says BenchmarkOTLPProtoSize/1span is 7.6% to 8.0% faster than its baseline. Eleven days after #4891 was opened, on #4926, the bot said the same sub-benchmark was 8.1% to 8.5% slower. Both comments are correct arithmetic over two sets of runs, and the baselines differ: 05d9b8a on the first, 1e830f6 on the second. Same benchmark, opposite verdicts. 🔀 ...

August 1, 2026 · 8 min · 1488 words · Kemal Akkoyun